AI Topics
Artificial Analysis v5 Shows Why AI Benchmarks Are Becoming Measurement Products
Artificial Analysis v5 highlights the benchmarker’s dilemma: useful scores must be stable, current, and resistant to gaming at the same time.
Read Article →
8 articles
Artificial Analysis v5 highlights the benchmarker’s dilemma: useful scores must be stable, current, and resistant to gaming at the same time.
Allen AI’s LitPivot shows how research agents can develop ideas by changing context as the literature changes.
OpenAI is restarting frontier-model training without live internet access, turning model security into a systems-engineering constraint.
Hugging Face’s report on fine-tuning Nemotron for IOI and IMO examines how training changes reasoning performance and why gold-level results need context.
Anthropic’s Claude Opus 5.5 cuts claimed serving cost and improves coding and agentic performance, raising new questions about evaluation and safeguards.
OpenAI’s GPT-6 Astra pairs faster computer work and persistent context with better alignment, but its safety tests show declining monitorability.
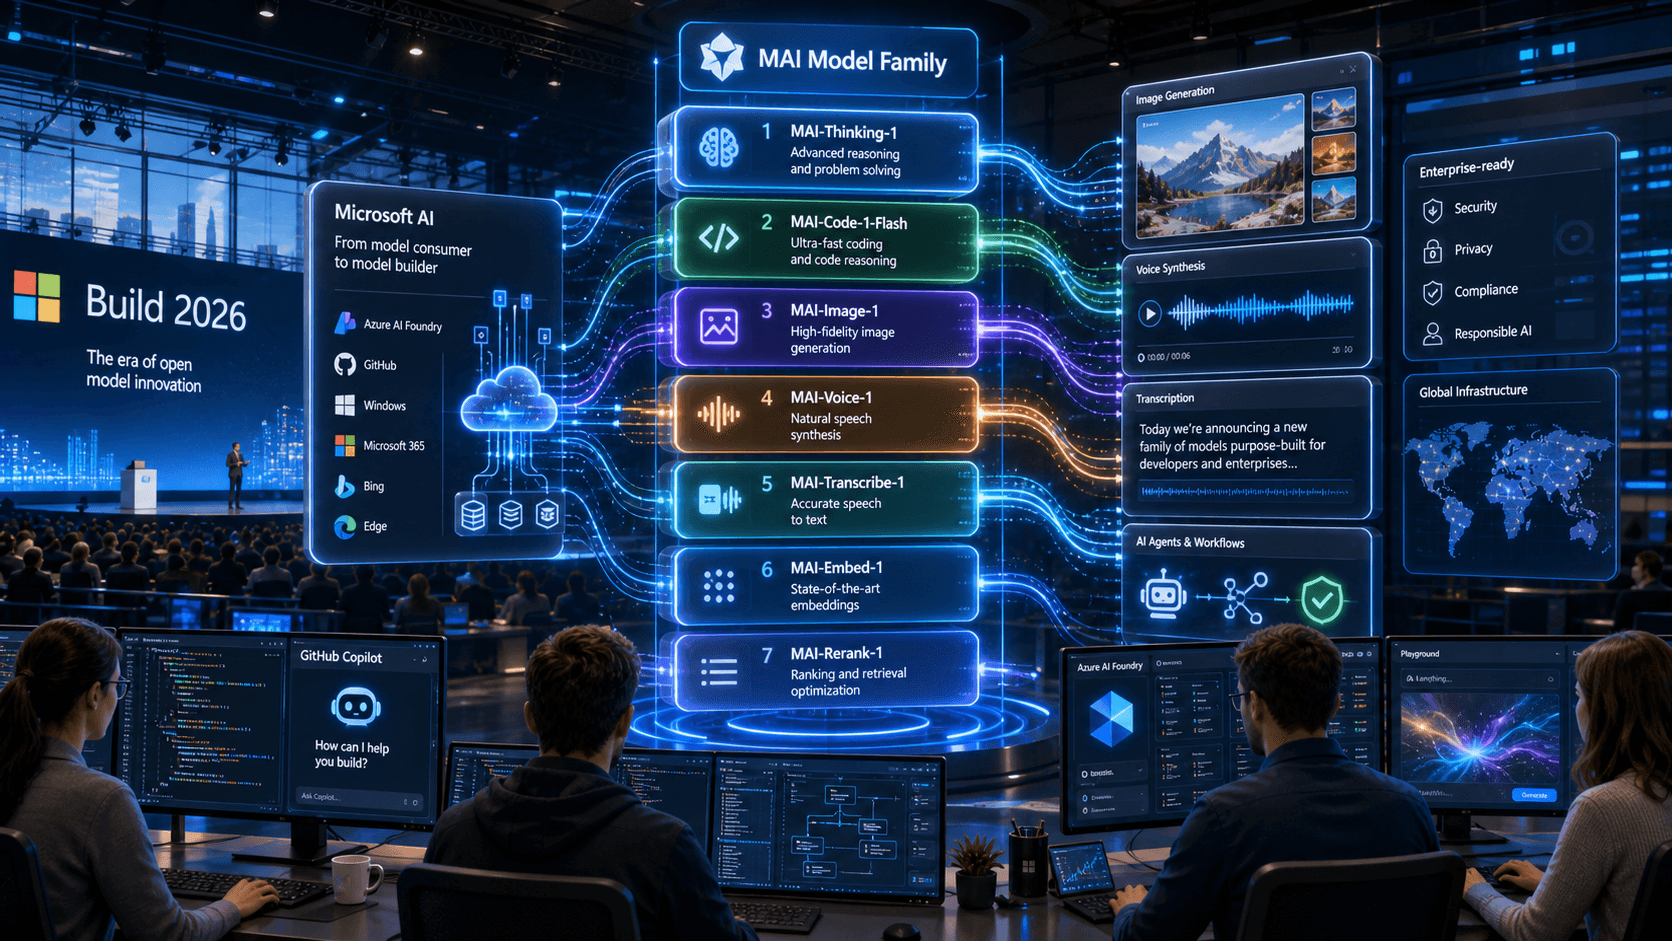
Microsoft's MAI model family signals a deeper Agentic AI platform strategy across coding, reasoning, voice, image, transcription, and developer workflows.
# The Open Titans: DeepSeek-V3 vs Llama 4 — The 2026 State of Open Weights In 2024, if you wanted performance, you went Closed. In 2026, if you want *optimizat...